Back to papers 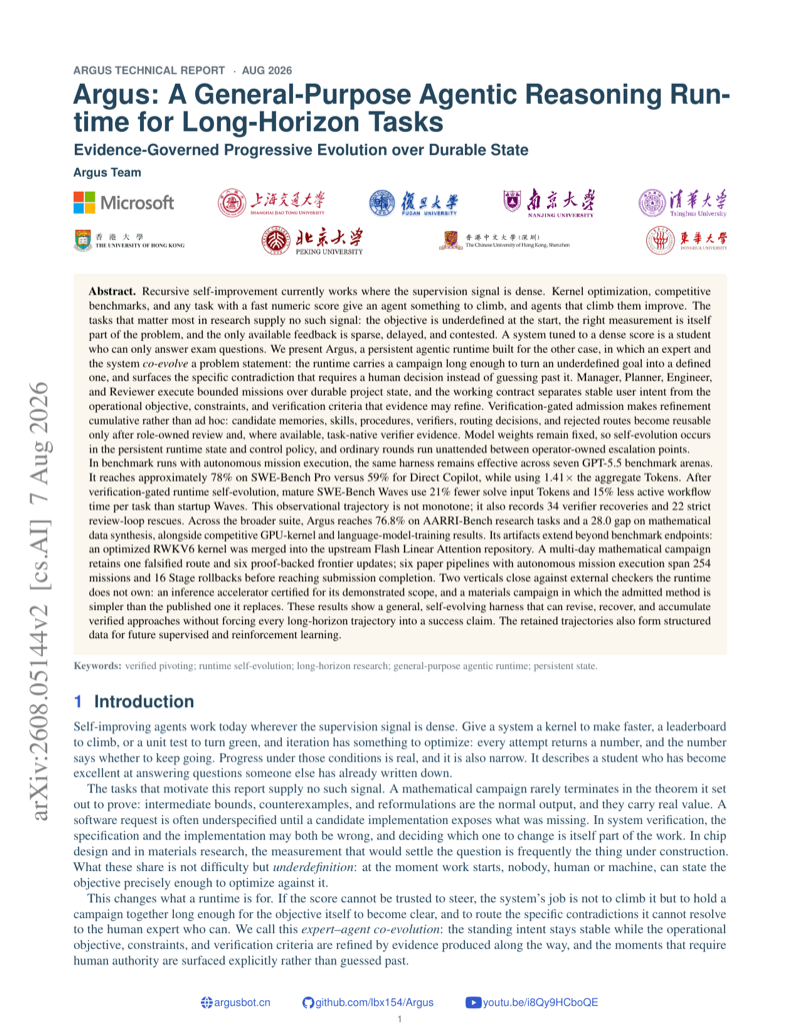
Want to read
Argus: A General-Purpose Agentic Reasoning Runtime for Long-Horizon Tasks
Argus is a persistent agentic runtime designed for long-horizon tasks with sparse feedback. It employs four roles to co-evolve problem statements while keeping model weights fixed. The system uses verification-gated admission to ensure cumulative refinement. Benchmarks show Argus achieves 78% on SWE-Bench Pro, outperforming Direct Copilot. The runtime supports self-evolution, reducing token usage and workflow time in mature waves.
Read the paperKey takeaways
- Argus utilizes a Manager, Planner, Engineer, and Reviewer to execute bounded missions over durable project state.
- The system achieves approximately 78% on SWE-Bench Pro compared to 59% for Direct Copilot using 1.41 times the aggregate tokens.
- Mature SWE-Bench Waves use 21% fewer solve input tokens and 15% less active workflow time per task than startup Waves.
- The runtime recorded 34 verifier recoveries and 22 strict review-loop rescues during observational trajectory analysis.
- Argus reaches 76.8% on AARRI-Bench research tasks and demonstrates a 28.0 gap on mathematical data synthesis.
- Artifacts include an optimized RWKV6 kernel merged into Flash Linear Attention and six paper pipelines spanning 254 missions.
Reflections
No notes on this one yet. I add reflections as I finish or revisit a paper.